
GenAI document processing
GenAI document processing for document-heavy workflows
GenAI document processing uses OCR, NLP and large language models to read documents, extract and classify their data, and summarize or route them with far less manual effort. HabileLabs builds these pipelines into your ERP, CRM and enterprise systems, on AWS, Azure or on-premises.
- 2.8 lakh documents masked in one week
- Fully offline option
- AWS, Azure or hybrid
What we automate
Document processing services
Document AI strategy
An assessment of your document landscape to choose the right AI pipeline for your unstructured data.
Intelligent data extraction and classification
GenAI, OCR and NLP that extract text and key information from unstructured documents with higher accuracy.
Content discovery and tagging
AI tagging and classification that make massive content libraries searchable.
Automated indexing and searchability
Hyper-tagging engines for rapid indexing, tagging and classification, managed in one central system.
Document intelligence in ERP and CRM
Classification, contextual approvals and intelligent routing inside ERP, CRM and enterprise systems.
Summaries and semantic retrieval
Key information extracted, indexed and summarized, with context-aware search for fast retrieval.
How it works
How GenAI document processing works
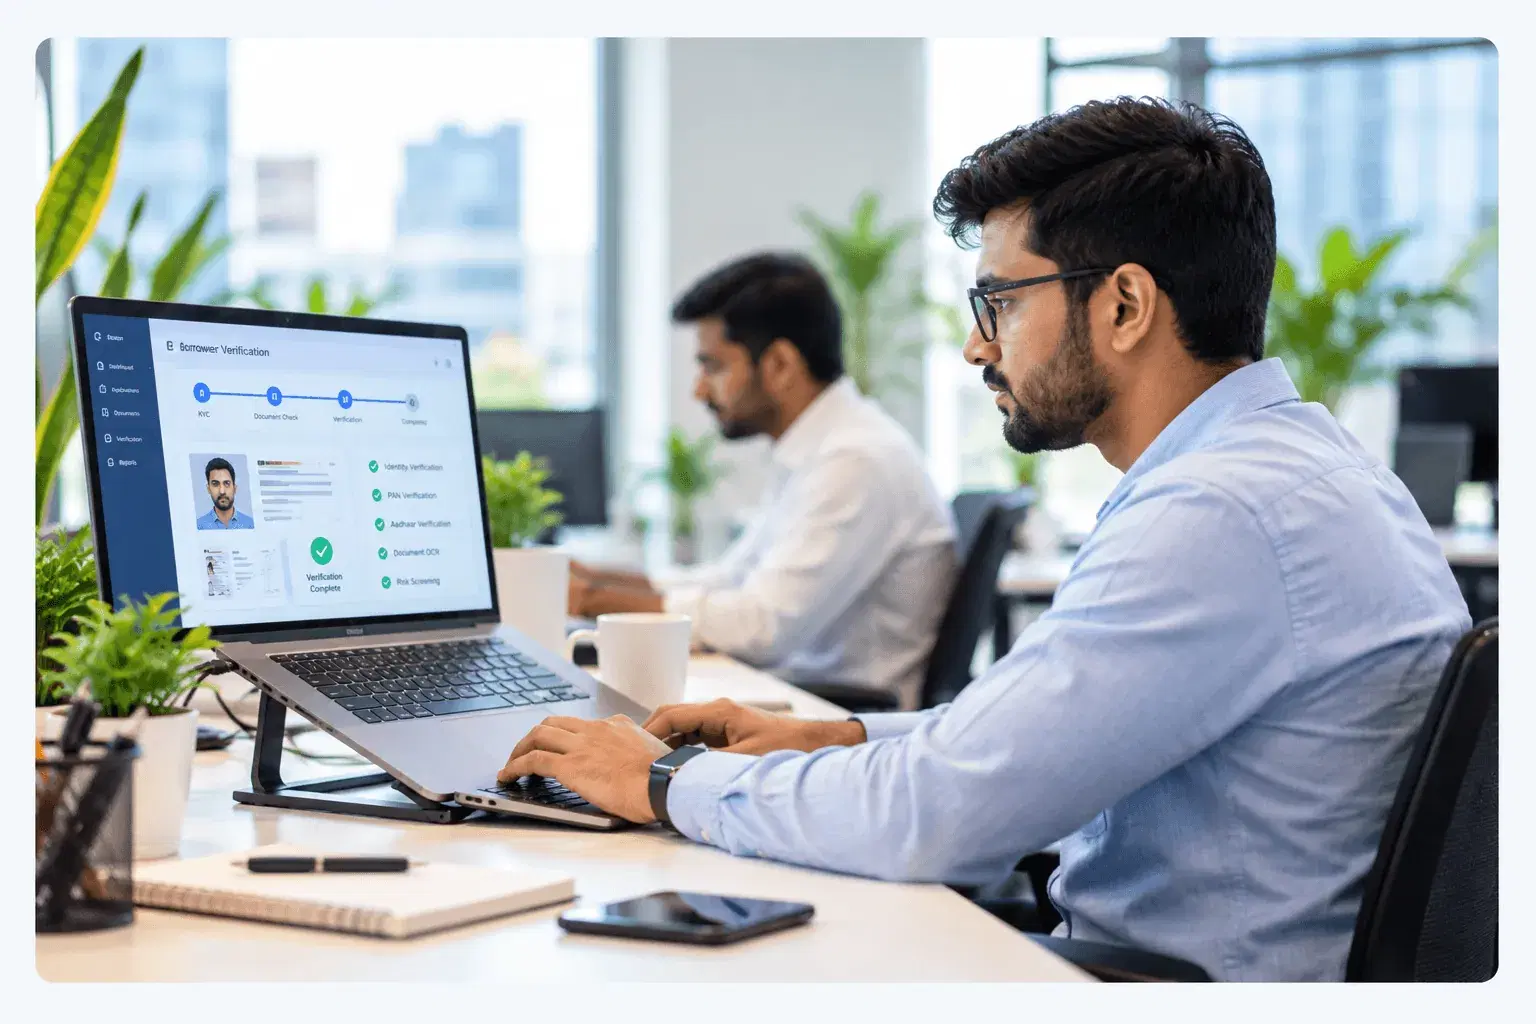
Large language models replace manual reading and re-keying, and the results flow straight into the systems your teams use.
LLM-based automation
Large language models extract, classify and summarize content from unstructured documents.
Prompt-based interface
Teams search documents in plain language and get context-aware results.
Low-code integration
Outputs connect to approval, routing and reporting flows through APIs.
Real-time content enrichment
Documents are tagged, indexed and enriched as they are processed, so they are searchable straight away.
Platforms and tools
Built on the document AI stack you choose
Pipelines run on AWS, Azure, hybrid or on-premises infrastructure, with continuous monitoring and governance.
Document AI services
Secure, scalable integrations with cloud and on-premises systems.
Search and knowledge retrieval
Search indexes across millions of documents.
Custom model training
Domain-adapted models for your document types.
Delivery channels
Outputs in dashboards, portals, mobile apps and workflow engines.
Hosting and operations
Continuous monitoring and governance.
Insights from document data
Extracted data turned into decisions.
Related products and work
Products and projects behind this service
Aadhaar Masking API
Masks every Aadhaar number and QR code in KYC and loan files: 99.94% of numbers and 100% of QR codes on 10,001 real loan files.
Explore the Aadhaar Masking APIDocuSwift
A serverless document management system for audit-ready loan files in your own AWS account.
Explore DocuSwiftAavas Financiers: loan file summaries
Amazon Bedrock summarizes loan applications and supporting documents inside Aavas' DMS for faster loan decisions.
Read the case study
Document processing FAQs
Document processing: common questions
It is the use of OCR, NLP and large language models to extract, classify, index and summarize information from documents, so document-heavy workflows run with less manual effort.
Unstructured documents such as PDFs, scanned images and text files, including loan applications, KYC documents, financial statements, credit reports and bank statements.
Yes. For Utkarsh Small Finance Bank, the masking pipeline ran fully offline inside the bank, with no internet access at any point, and processed 2.8 lakh documents in one week.
It depends on the documents. On published projects, HabileLabs reports 99% Aadhaar masking accuracy for Utkarsh Small Finance Bank and 95% across 1.5 million documents for Choice Finserv.
Yes. We embed document intelligence into ERP, CRM and enterprise systems for classification, contextual approvals and routing, and send outputs to dashboards, portals and mobile apps.
On AWS, Azure, a hybrid setup or on-premises, using Docker, Kubernetes or serverless frameworks with continuous monitoring and governance.